Relative positional embeddings with RoPE
Word order matters to a language model. In this post I'll explain RoPE: a technique that makes attention between two tokens depend on the distance between them instead of their absolute sentence position.
Self-attention is a core part of modern transformer-based language models. Self-attention adjusts the embedding of each token (or word) using the embeddings of its neighbors, so the token absorbs the context of its sentence. For example, the word "station" means different things in the sentences "I am listening to a radio station" and "I just left the train station".
Self-attention by itself is order-agnostic and would compute the same results for the sentence "left train I station the just" or "I just left the train station". That is a problem, because word order matters in language. How do we ensure that self-attention will consider token positions?
Position as a sinusoidal signal
The trick presented in the original "Attention is all you need" paper is to encode the position of a token into the embedding before computing attention values (Vaswani et al. 2017). These position encodings, or positional embeddings, come in several forms; a popular one is the sinusoidal positional embedding. The d-dimensional positional encoding for a position n is defined as follows:
Let's plot these values for varying n and i to see what this encoding looks like.

The encoding lies in the range [-1, 1], and the lower embedding dimensions oscillate faster than the higher ones. This is similar to binary numbers, where the least significant bits flip far more often than the most significant bits (Bishop, 2023). This positional embedding vector is added to a token embedding before computing attention:
This approach encodes the absolute position into the token embedding. In many sequences, the relative ordering of words or tokens is more important. For example, in the sentences "I just left the train station" and "Because I was late, I left the train station," the link between "train" and "station" is the same, though the words sit at different positions in each.
This is where "Rotary Positional Encodings" (RoPE) come in (Su et al. 2023). RoPE similarly uses a sinusoidal signal to encode the position. However, instead of adding this signal to the original input vector, RoPE multiplies the sinusoidal signal with the input after projection into query or key space. For example, to compute a position-adjusted query vector from the original token at position , with the embedding dimension :
Those familiar with linear algebra might recognize the rotation matrix. The input thus gets rotated, by an angle that depends on the token position . We generalize to embedding dimensions greater than two by expanding matrix as follows:
Pairs of features get rotated with varying base frequencies . is defined similarly as in the absolute positional embeddings, with lower embedding dimensions rotating more quickly than higher embedding dimensions:
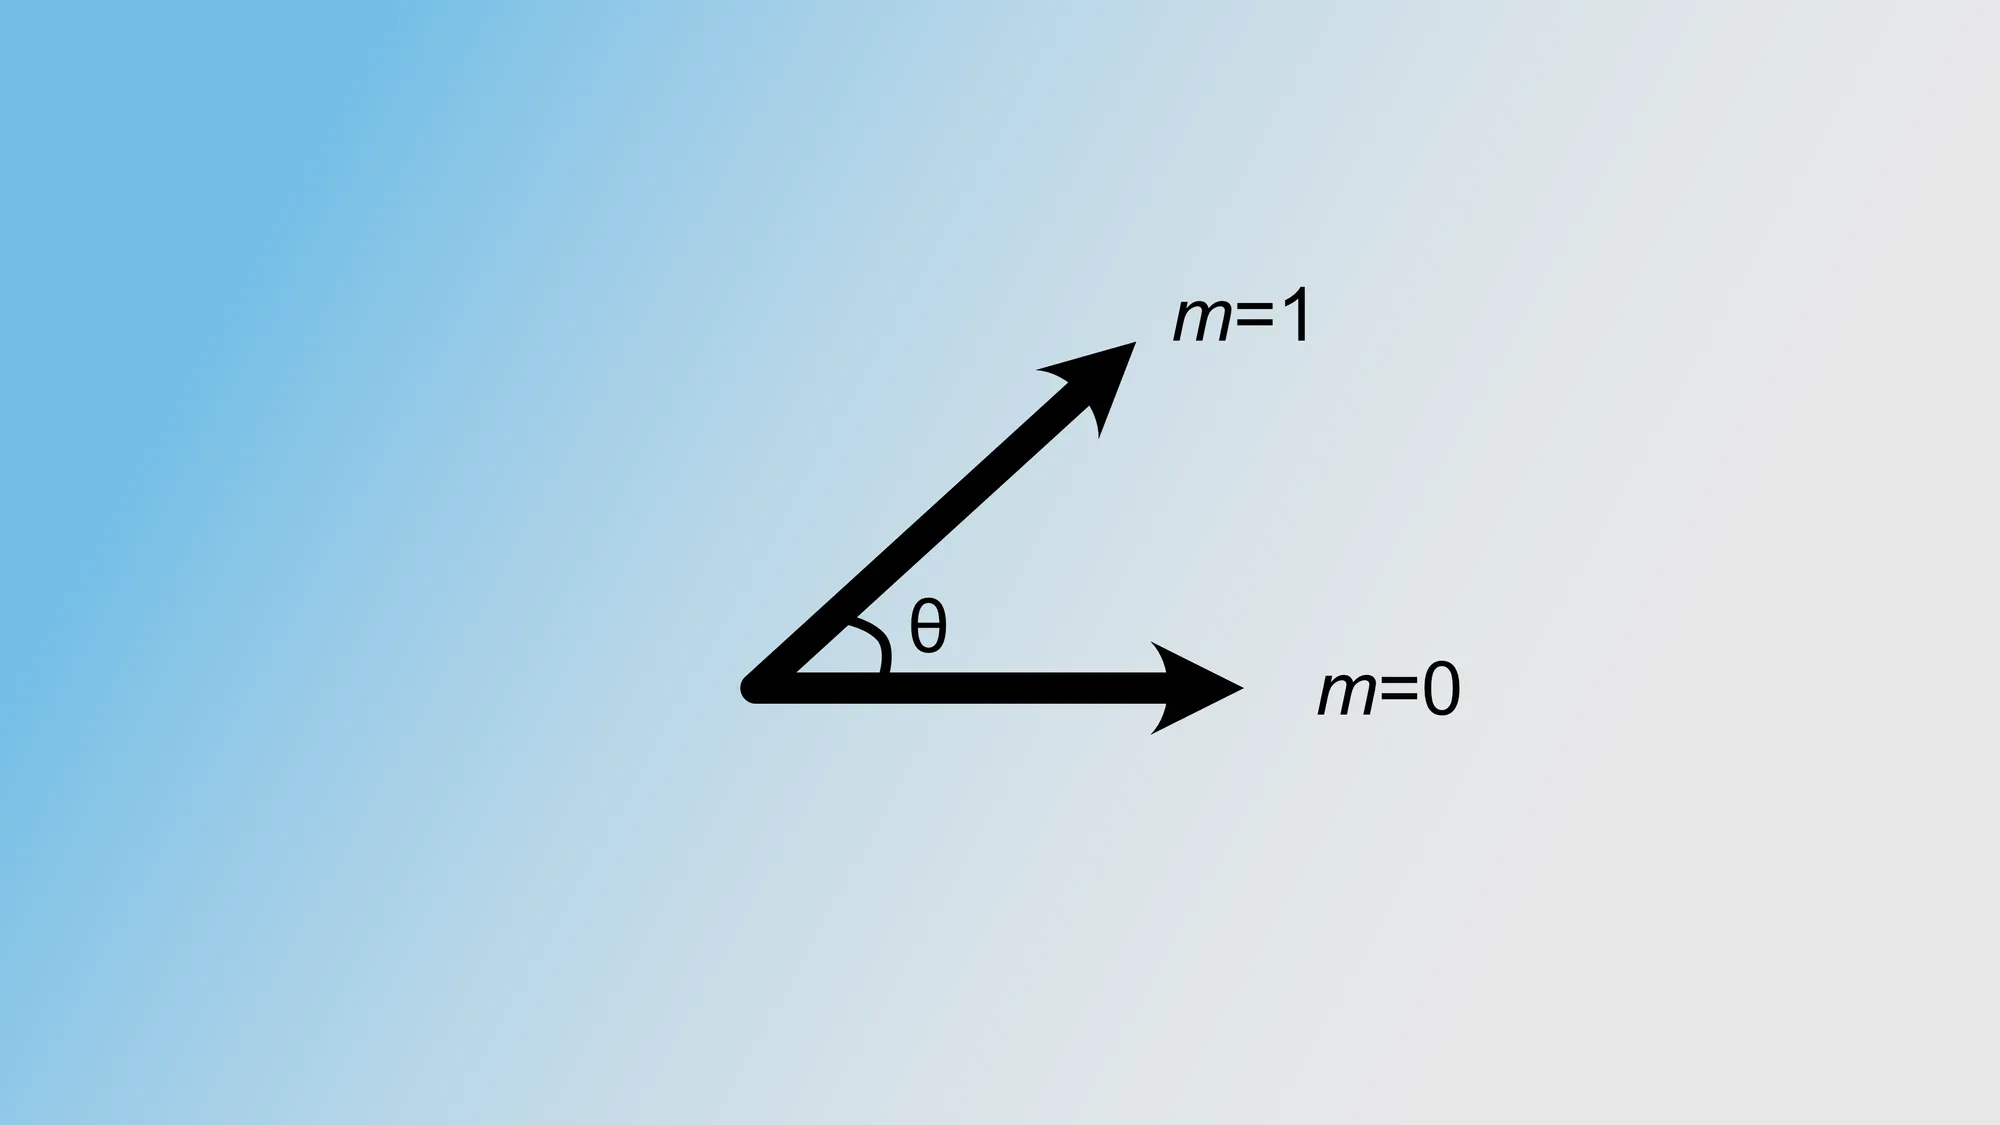
Rotated vectors have a benefit: the angle between two position-adjusted vectors at and will only depend on their relative position, not on the absolute positions and .
Interpreting input features as complex numbers to derive the RoPE equation
How did RoPE's authors arrive at its rotation equation? To explain its derivation, let's recall that the attention weights are computed by taking the softmax of the inner product between query and key vectors. In the case of self-attention, the query and key vectors are derived from different tokens in the sequence:
When using absolute positional encodings, the query and key vectors will be derived from the position-adjusted vector . For RoPE, we aim to find an alternative function to encode positional information, such that the inner product between two position-adjusted vectors only depends on the relative position between two tokens. Mathematically, the following should hold:
To derive such a function, we turn to the complex domain. A d-dimensional vector can be interpreted as a complex (d/2)-dimensional vector . For example:
A complex number can alternatively be written in polar form , where and are called the radial and angular part of a complex number, respectively, and which are defined as and .
The standard inner product on is defined as , that is, taking the complex conjugate and transpose of before multiplication with . Using this definition, and writing the complex numbers returned by and in polar form, we can get the following:
Here we have explicitly written the inner product between two complex numbers on the left-hand side, equating it to a complex number on the right-hand side, representing . We have also defined functions , , , and , representing the radial and angular part of the complex numbers returned by and , respectively.
The conjugate of a complex number in polar form is . With this definition, we can further simplify the left-hand side of Equation 2 by combining the product of two complex numbers:
Equating the radial and angular part in Equation 3, we get:
To make functions and more concrete, we start with a few simple initial conditions. Let's require that a token at the start of a sequence is unmodified by our positional embedding: . Here can refer to or . We also define , that is, , and , where is the angular part of , that is the angular part of the reinterpreted values of or as a complex number.
Now, let's assess the case when :
Here, we have applied Equation 3 to get the result , and applied it another time to get . We use our initial condition definitions to get the final result.
Equation 4 must hold for all token positions ; the final result, however, doesn't depend on . Thus .
What can we infer for the angular part when ? Applying Equation 3 as we did for the radial part, we get:
Rearranging terms of the first and last part of Equation 5, we get:
This holds for all and , which implies that the change in the angular part of the position-adjusted complex number is independent of the or .
This insight gives us some freedom to define . For example, we can define it as follows:
In other words, we add a position-dependent value to the original angular part . But what would be? We can gain some insight by analyzing the difference between two subsequent positions, that is the case when .
Here we moved and to the left-hand side to get an expression for . By applying Equation 3, we transformed the left-hand side to an expression that does not depend on . This implies that the difference does not depend on either, and can be constant. We can define as a simple arithmetic progression:
In this definition, and are free to choose. For example, we can set to an embedding-dimension-specific value, and set .
Combining all pieces, we arrive at the following:
Through our constraint on relative position and a few simple initial conditions, we were able to define a simple expression that encodes the sequence position into a query or key vector. Finally, using Euler's formula, we get the rotation matrix we discussed at the beginning of this post:
Conclusion
Token order matters in language and in biological sequences. RoPE requires the inner product of position-adjusted query and key vectors to depend only on relative position, and that leads to a simple transformation: rotating input vectors in the complex domain. So when "train" and "station" sit side by side, attention sees them as neighbors, wherever in the sentence they fall.
References
Bishop, C. M., Bishop, H. & Cham, S. (ed.) (2023). Deep Learning - Foundations and Concepts. ISBN: 978-3-031-45468-4
Su, Jianlin, Yu Lu, Shengfeng Pan, Ahmed Murtadha, Bo Wen, and Yunfeng Liu. “RoFormer: Enhanced Transformer with Rotary Position Embedding.” arXiv:2104.09864. Preprint, arXiv, November 8, 2023. https://doi.org/10.48550/arXiv.2104.09864.
Vaswani, Ashish, Noam Shazeer, Niki Parmar, et al. “Attention Is All You Need.” arXiv:1706.03762. Preprint, arXiv, August 2, 2023. https://doi.org/10.48550/arXiv.1706.03762.