Relative positional embeddings with RoPE
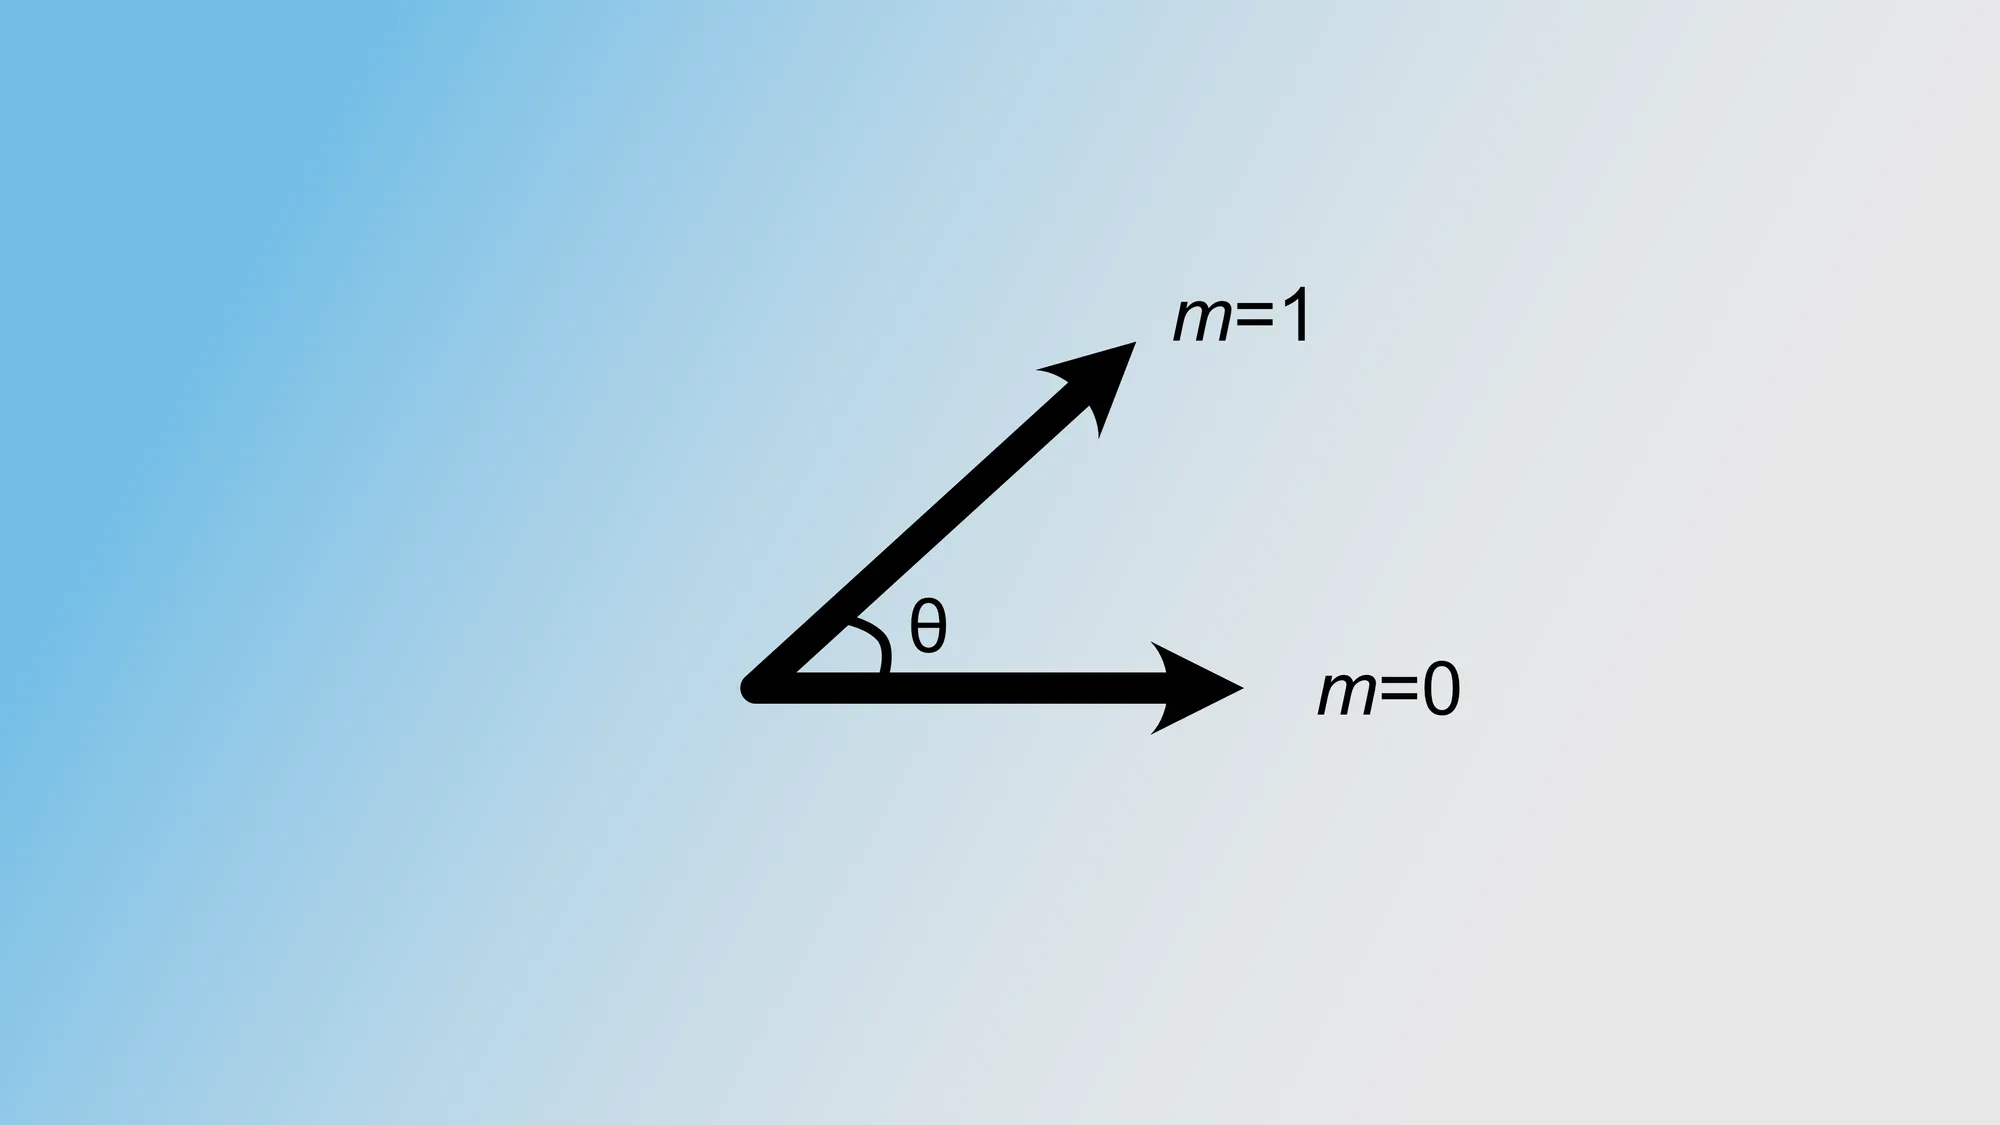
In language models, the order of tokens is of critical importance. This post explains RoPE: a technique that ensures that the pairwise token attention weights depend on their relative position to each other instead of absolute position in the sequence, improving generalization.