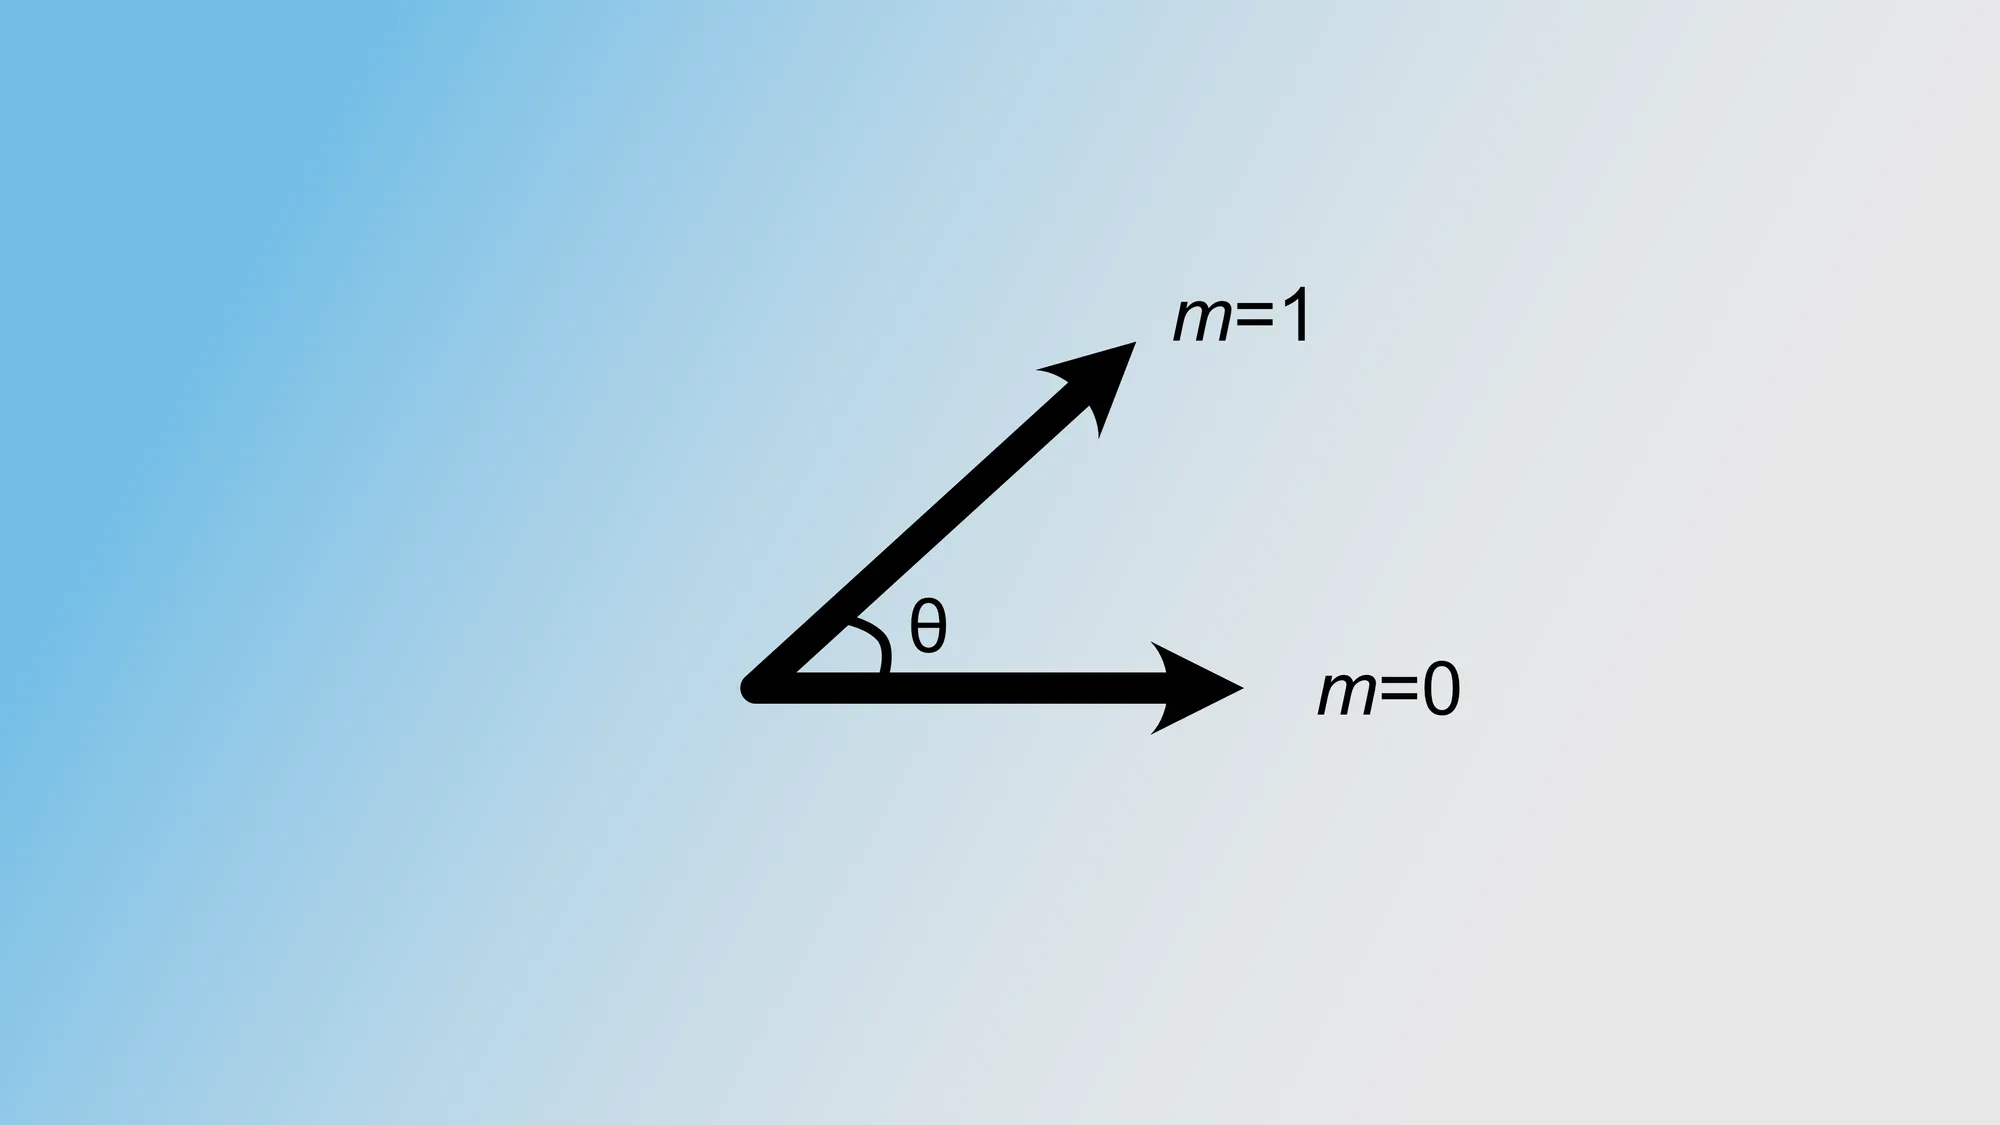
In language models, the order of tokens is of critical importance. In this post I'll explain RoPE: a technique to ensure the pairwise token attention weights depend on the relative position to each other instead of absolute position in the sequence, improving model generalization.
Relative positional embeddings with RoPE